Daniel Saks
Chief Executive Officer


Software engineering has SWE-bench, developed at Princeton to measure how coding agents handle real GitHub issues. Language models have MMLU and a dozen successors. Go-to-market work has had nothing of the kind. Buyers evaluate list-building tools on database size, filter counts and coverage claims, and those numbers predict almost nothing about what reaches the sales floor.
The 2026 GTMBench was built on the SWE-bench model. 26 real list-building prompts, fixed before any vendor ran. One automated attempt per prompt. Every returned row re-scraped from LinkedIn and judged row by row against the same criteria by the same model. Salesforce State of Sales research reports that reps spend only 28% of a working week actually selling, with most of the remainder absorbed by list hygiene and re-verification. Harvard Business Review coverage of B2B selling documents the same pattern. GTMBench measures the metric that governs how much selling actually happens: how clean is the list that a vendor hands to a rep. The full report lives on the GTMBench landing page.
The headline number in most prospecting evaluations is catalog scale. Apollo publishes 240 million contacts. ZoomInfo aggregates business intelligence at similar scale. Clay reaches more than 200 data providers through its marketplace. Buyers see those numbers and infer coverage.
Coverage is not precision. GTMBench measured that gap. ZoomInfo's filters matched a geometric mean of 60,314 records per prompt, 46x Landbase's 1,304. ZoomInfo's precision came in at 23.2%. Landbase's at 76.7%. The pool is much larger. The yield after verification is much smaller. Expected true matches came in at 4,868 for ZoomInfo against 846 for Landbase, closer than the pool sizes suggest.
Catalog scale and verified yield are different measures. A benchmark that only reports catalog scale answers a different question than the one buyers care about.
The benchmark used 26 prompts drawn from a corpus of 50,000 natural-language queries that Landbase operators had run on the platform. The prompts cover four families: firmographic (facts a vendor already stores, like industry and headcount), derived (facts a vendor would have to compute from raw data), lookalike (a seed set plus find more like these) and concept (loose labels like sticky brands or creator economy startups).
Four systems were in the set: Landbase, Clay, Apollo and ZoomInfo. The four cover the three ways list-building work gets done today. Apollo and ZoomInfo are catalogs with fixed filter dropdowns. Clay is a workflow builder that reaches further through multi-step pipelines. Landbase is an agent that takes the prompt in plain language and reasons over the data.
Each competitor was driven by a fresh coding agent reading only that vendor's own API documentation. That measured what a capable new user gets on the first attempt, not what a seasoned power user coaxes out of the platform after months of tuning.
Precision is the share of returned rows that met every criterion. Landbase scored 76.7% precision across all 26 prompts. Clay 47.9%. Apollo 36.0%. ZoomInfo 23.2%. On the first 100 rows, Landbase scored 76.1%, Clay 40.6%, Apollo 29.2%, ZoomInfo 18.3%. The first-100 number matters more because that is the page a rep works in week one.
Qualified recall share measures how qualified rows split across the four vendors within a prompt. The share sums to 100% within a prompt, so above 25% is more than an even share. Landbase scored 47% across all 26. Clay 24%, Apollo 19%, ZoomInfo 10%.
Pool size captures reach: how many records the vendor's filters matched before the row cap. ZoomInfo's 60,314 and Apollo's 13,519 dominate on reach. Landbase's 1,304 trails. Expected true matches multiplies precision by pool, which captures the qualifying companies each vendor reaches. ZoomInfo 4,868, Apollo 3,764, Landbase 846, Clay 190-plus.
Time to list measures seconds from prompt to finished list. Clay 17, Apollo 20, ZoomInfo 20, Landbase 134. The agent takes seven times longer than any catalog. The extra time is where the precision gap comes from. Gartner research on sales technology adoption has argued that buyers trade latency for accuracy when the downstream cost of a bad list is high.
Judging precision cleanly is where most industry comparisons fail. GTMBench built the judging layer on the SWE-bench pattern. Each vendor's list and the Landbase list were split into the rows they share and the rows only one of them found. The same model judged every segment: 100 rows per segment, scored against the original prompt criteria, re-scraped from LinkedIn at judgment time.
None of the judging time counted toward any vendor's time to list. Judging consistency across segments comes from using the same model with the same criteria rubric, instead of relying on human raters who vary across sessions.
The row-level judgment is where catalog claims come apart. A vendor can hold a company record that nominally meets the criterion. Re-scraping from LinkedIn at judgment time tests whether the record is current. A stale catalog loses rows at this step.
The Landbase AI Lab designed and ran the benchmark. The report is published for buyers and operators who want a measure of what each system returns under the same conditions. McKinsey research on sales productivity has argued that benchmarks created by platform operators carry obvious orientation, which is why GTMBench publishes the methodology, the prompts and the per-prompt scores.
Every row the four systems returned is listed in the full report. The judging rubric and the LinkedIn re-scrape pattern are documented. Future editions will add systems and expand the prompt set as new patterns surface in operator data.
Three measures separate systems on dimensions that catalog claims do not predict. First-100 precision describes the top of the file. Precision-across-26 describes consistency. Expected true matches describes qualified reach after verification.
A buyer who optimizes for raw reach reads expected true matches and tolerates lower precision in exchange for pool size. A buyer who optimizes for SDR productivity reads first-100 precision and accepts a smaller pool for a cleaner top. The two choices lead to different stacks.
GTMBench does not resolve the choice. It makes the trade-off visible. For the vendor-by-vendor view, read our Landbase vs Clay, Landbase vs Apollo and Landbase vs ZoomInfo comparisons.
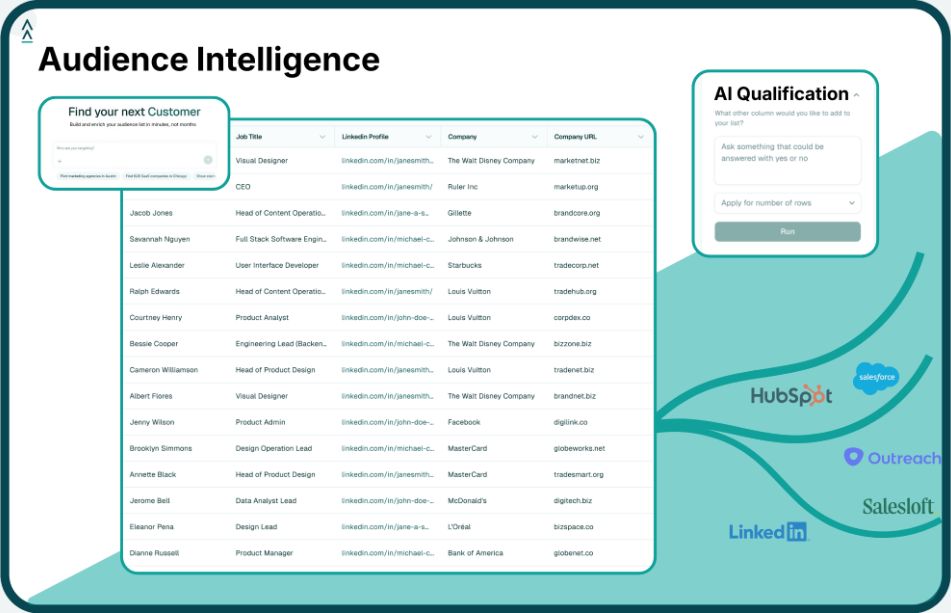
Landbase is an agent that reads a plain-language prompt, reasons across more than 1,500 enrichment fields per company, verifies each row before returning it, and dial-tests the file before handoff. The platform runs inside Claude Code and Codex, and connects to Salesforce, HubSpot and CSV export. HubSpot sales statistics have documented how much of an SDR week depends on list quality upstream of the dial.
Across GTM teams from agencies to enterprise revenue organizations, customers have reported a 2 to 4x uplift in connect and meeting-booked rates. Send Landbase a list already pulled from Clay, ZoomInfo or Apollo and the platform will qualify, expand and score it in one pass at no cost. Start a qualification pass here.
Each competitor was driven by a fresh coding agent reading only that vendor's own API documentation. That measures what a capable new user gets on the first attempt. Human operator tuning across many sessions would likely raise all four vendors' numbers; the benchmark isolates the out-of-the-box precision.
Each prompt required judging every returned row, up to 1,000 per vendor per prompt, by re-scraping from LinkedIn. 26 prompts across four vendors produced over 100,000 row-level judgments. The 26 were chosen to represent the four prompt families proportionally. The number is a cost-of-judgment constraint, not a measurement limit.
Catalog freshness is one of the things the benchmark measures. A stored attribute that no longer matches the LinkedIn profile fails the criterion the prompt actually asks for. Judging from current LinkedIn state puts all four systems on the same reference data.
Yes. The benchmark pattern is annual. Future editions will add systems (new entrants that emerge in the market) and expand the prompt set as new patterns surface in operator data.
The full report is at landbase.com/gtmbench. The methodology, the 26 prompts, the per-prompt scores and the four summary measures are all documented.
Tool and strategies modern teams need to help their companies grow.