Daniel Saks
Chief Executive Officer


Catalog systems answer prompts by matching stored attributes. If a buyer asks for software companies in San Francisco with 50 to 200 employees, every value in the prompt sits in a stored column, and a filter dropdown returns the matching rows. If the buyer asks for software companies whose engineering tenure distribution shifted sharply in the last quarter, no column stores that value, and the catalog has nothing to resolve the query against.
The 2026 GTMBench included 8 derived prompts across the 26-prompt set to probe this boundary. Landbase scored 75.6% precision across the family. Clay scored 18.2%. Apollo 7.8%. ZoomInfo 4.8%. Forrester research on B2B data readiness has argued that enterprise buyers increasingly ask questions their vendor catalogs cannot answer. Harvard Business Review coverage of B2B selling documents the same gap in enterprise sales. This post walks through the derived family, what makes a prompt derived, and why the gap is structural rather than a tuning problem. The full methodology lives on the GTMBench landing page.
A prompt is derived when its criterion is a value computed from underlying records, not a value stored in a catalog column. Four shapes of derived criteria appeared in the benchmark.
Trends over time compare a value at two moments. LinkedIn followers grew more than 20% last quarter requires the follower count at the start of the quarter and at the end, and the ratio. No catalog stores historical snapshots of the follower count as a queryable field.
Distributional measures compute a statistic across many values within a company. 90th-percentile engineering tenure under 18 months requires ranking tenure across the engineering function and reading the 90th percentile. Catalogs store individual tenure, not company-level percentiles.
Ratios across people within a company compute one count over another. AE-to-SDR ratio between 1.5 and 3 requires enumerating both roles and dividing. Catalogs store role headcount at the company level but do not store ratios between roles.
Composite labels collapse several signals into one. Series A to C companies where engineering is 40% or more of headcount combines a funding stage with a function-share measure. Each piece sits somewhere in a catalog. The combined measure does not.
The derived family in GTMBench included the three that broke Clay and ZoomInfo (follower growth, tenure percentile, AE-to-SDR ratio), plus five more that stressed the family in different ways. Series A to C companies where engineering is 40% or more of headcount. Crypto companies that laid off in 2023 but are growing again. A CRO joined a Series C or later SaaS company in the last 12 months. B2B software companies with an SDR to AE structure. First engineering hires near Austin.
Each criterion requires computation across underlying records. The CRO prompt requires detecting both the role transition and the funding stage. The crypto prompt requires detecting both a layoff event in 2023 and a growth signal in the current period. The engineering share prompt requires computing a function-level ratio.
Landbase scored above 85% on seven of the eight derived prompts. Clay scored above 40% on one. Apollo above 20% on two. ZoomInfo above 10% on none.
A workflow builder like Clay composes against the catalog layer. The marketplace of 200-plus data providers includes a wide range of stored attributes. The composition can chain many of them into a single pipeline step. If no provider stores the specific attribute (and none in the current marketplace stores follower growth as a time series or tenure as a distribution), the composition has nothing to compose from.
The structural limit is the schema, not the composition logic. A workflow builder with twice as many steps or ten times the data providers would still return nothing on a prompt whose target value is not stored anywhere in the schema. Gartner research on sales technology adoption has observed that buyers increasingly ask questions outside their vendor catalogs' pre-defined axes, and that the gap widens as sales motions move toward trigger-based outbound.
A reasoning agent like Landbase reads underlying records at list-build time and computes the derived measure per company. The computation happens at the prompt layer. The system is not restricted to pre-stored attributes because it does not query against them.
Derived criteria concentrate in sales motions that depend on triggers rather than static firmographics. A list of software companies at a given size captures a population. A list of software companies at that size whose engineering roster turned over in the last 12 months captures a subset where a specific trigger has fired.
The subset is the file reps want to work. LinkedIn research on sales trends has documented how buyer organizations grow attention and headcount in parallel with buying signals. Triggered outbound outperforms non-triggered outbound on every measured conversion metric. Triggers are derived. Catalogs store state, not change.
Teams that run triggered motions encounter the derived gap on nearly every prompt. Teams that run static firmographic motions encounter it rarely. The vendor evaluation depends on which share of the team's working lists use derived criteria.
At list-build time, the Landbase agent parses the prompt and identifies the derived criteria. For a trend prompt, the agent fetches the value at two or more moments from the underlying record and computes the difference. For a distributional prompt, the agent enumerates the relevant population within a company and computes the statistic. For a ratio prompt, the agent counts the two populations and divides.
Each computed value is checked against the threshold the prompt specifies. Only companies where the computed value cleared the threshold return as rows. The verification pass against the current LinkedIn record happens on the computed value, not on a stored attribute.
The precision cost of this architecture is the runtime: Landbase takes 134 seconds against Clay's 17. The 134-second trade-off post covers the latency calculation.
Buyers evaluating prospecting tools often compare database size and filter count. Derived prompts show that both measures miss a structural capability. A tool with 10x the records and 10x the filters still returns 0 on a prompt that requires computing a value the schema does not store.
The gap matters most for teams whose best-performing lists use derived criteria. Hiring signals, team-mix ratios, growth-stage transitions, product-launch cadence, funding timing and executive-tenure patterns all require derivation. Teams whose outbound depends on those signals need a system that can derive at list-build time.
For teams whose motion is firmographic (industry, size, geography), catalog systems compete head to head. For teams whose motion depends on derived signals, the 57-point family gap in GTMBench suggests the structural limit is not closable through filter composition alone. See the three-prompts post for a deeper look at the specific cases where Clay and ZoomInfo returned nothing.
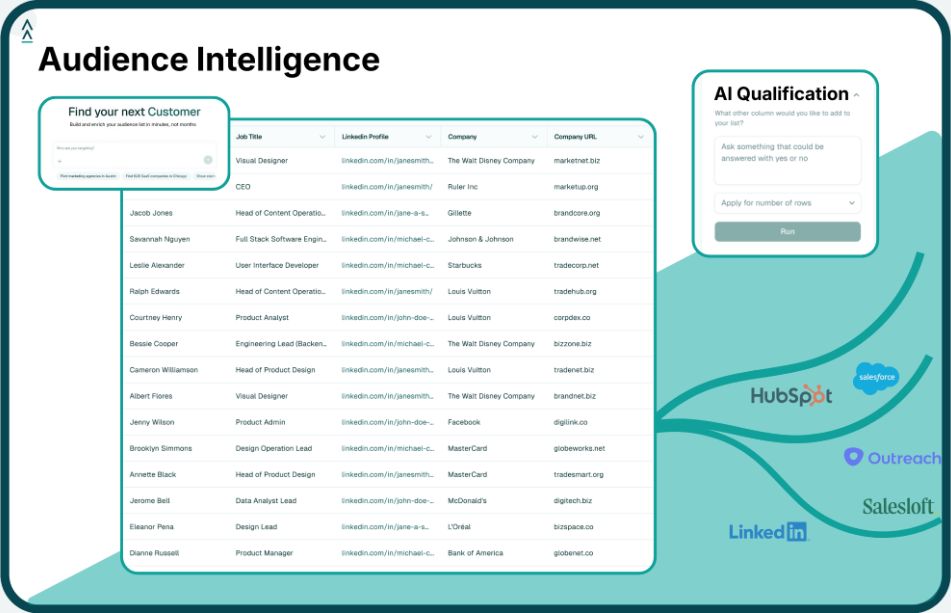
Landbase is an agent that reads a plain-language prompt, reasons across more than 1,500 enrichment fields per company, computes derived measures at list-build time, verifies each row before returning it, and dial-tests the file before handoff. The platform runs inside Claude Code and Codex, and connects to Salesforce, HubSpot and CSV export. HubSpot sales statistics have documented how much of an SDR week depends on list quality upstream of the dial.
Across GTM teams from agencies to enterprise revenue organizations, customers have reported a 2 to 4x uplift in connect and meeting-booked rates. If your best-performing lists use derived criteria, send Landbase the prompt and the platform will build and score it in one pass at no cost. Start a derived-criteria pass here. For the vendor-by-vendor view, read our Landbase vs Clay comparison.
Clay's AI research steps operate on top of the catalog composition. The research steps can enrich individual rows after the catalog returns them. On derived prompts, the catalog composition returns nothing (or returns rows filtered against the wrong attribute), and the research layer has nothing to enrich. Clay scored 18.2% average across the 8 derived prompts, mostly from the few prompts where catalog filters produced partial matches.
Partially. Apollo averaged 7.8% precision on the derived family. The AI research layer attempted computation on prompts the catalog filter alone could not reach, which raised precision above zero on several, but the gap to the agent approach stayed wide.
Not always. Firmographic prompts work well when the criterion is a stable attribute of the target company. Derived prompts work better when the criterion is a trigger or inflection point. The best-performing lists in trigger-driven motions use derived criteria. The best-performing lists in territory-driven motions use firmographic criteria.
Teams in GTMBench's operator corpus report the strongest lift on recency-of-funding, recent executive transitions, hiring velocity in a target function, and company-size inflection points. The specific lift varies by segment, but each of these criteria sits firmly in the derived family.
The full report, with every prompt scored across all four vendors and the family-level averages, lives on the GTMBench page.
Tool and strategies modern teams need to help their companies grow.